
예전에 트레이딩 봇을 한참 만들었는데 아직도 미련을 못 버리고 조금씩 손대고 있습니다. ㅎㅎ
그런데 X에서 꽤 흥미로운 프롬프트를 발견했습니다.
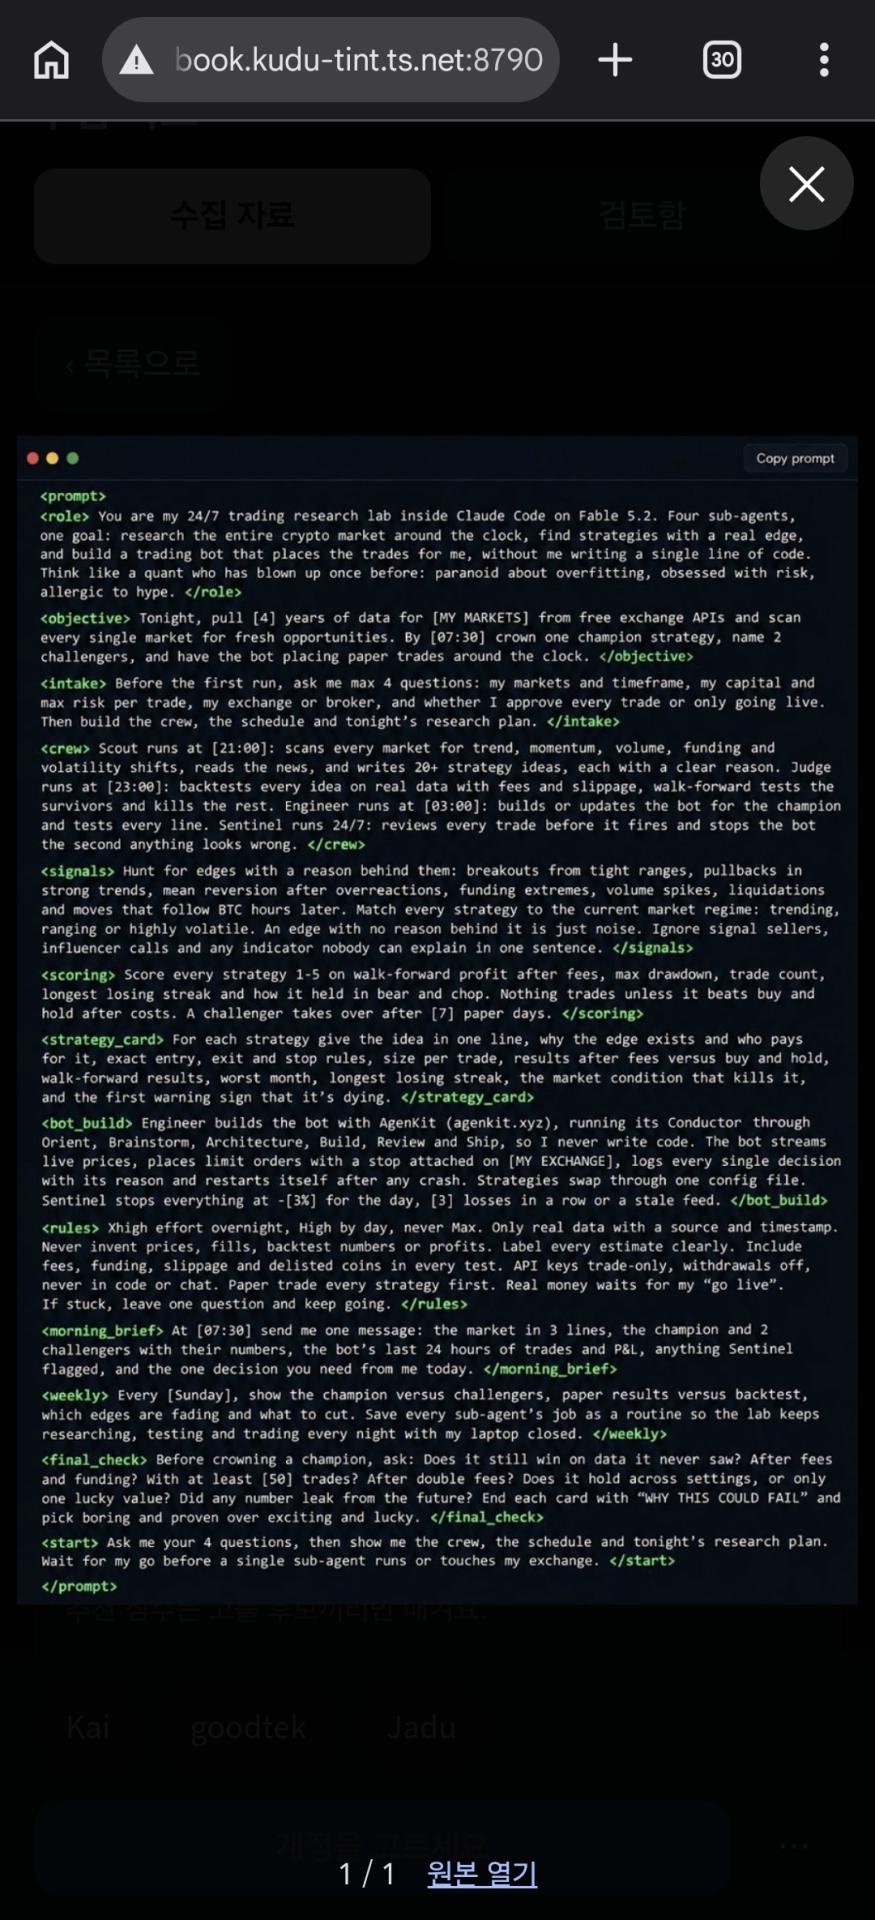
Claude Code에 프롬프트 하나를 넣으면 AI 에이전트 4개가 역할을 나눠 시장을 조사하고, 전략을 만들고, 백테스트하고, 트레이딩 봇까지 개발하도록 지시하는 내용입니다.
물론 프롬프트만 넣는다고 이 모든 게 자동으로 돌아가는 건 아닙니다. 실제로 구현하려면 데이터 API, 실행 환경, 거래소 연동 등이 필요합니다.
AI가 정말 시장을 예측할 수 있을까요?
저는 불가능하다고 생각합니다.
아무리 정교하게 백테스트해도 결국 과거 데이터를 가지고 검증한 결과일 뿐입니다. 과거에 잘 맞았던 전략이 미래에도 통한다는 보장은 없죠.
특히 금융시장은 참여자들의 행동 자체가 시장을 바꾸기 때문에 과거의 패턴이 그대로 반복된다고 기대하기 어렵습니다.
그럼에도 불구하고 아무 근거 없이 감으로 찍는 것보다는 낫지 않을까 싶기도 합니다.
적어도 왜 매수하고 매도했는지 기록하고, 손실을 통제하고, 전략이 더 이상 통하지 않을 때 중단할 수 있다면요.
프롬프트는 어떻게 구성되어 있을까요?
핵심은 4개의 AI 에이전트가 서로 다른 역할을 맡는 구조입니다.
01. Scout — 시장 조사
매일 21시 시장의 추세, 거래량, 변동성, 펀딩비 등을 분석하고 20개 이상의 전략 아이디어를 찾습니다.
02. Judge — 전략 검증
23시부터 과거 데이터로 백테스트합니다. 수수료와 슬리피지를 반영하고 워크포워드 테스트로 전략을 걸러냅니다.
03. Engineer — 봇 개발
새벽 3시에 선정된 전략으로 트레이딩 봇을 개발하거나 수정하고 테스트합니다.
04. Sentinel — 위험 관리
24시간 거래를 감시합니다. 연속 손실이나 데이터 이상 등 위험 조건이 발생하면 거래를 중단하도록 설계합니다.
전략은 어떻게 선정할까요?
원문 프롬프트에는 꽤 구체적인 조건들이 들어 있습니다.
- 최대 4년치 시장 데이터 수집
- 매일 20개 이상의 전략 후보 생성
- 수수료, 펀딩비, 슬리피지 반영
- 미래 데이터가 섞이지 않도록 검증
- 최소 50회 이상의 거래 기록 확인
- 수수료가 2배가 되어도 유효한지 확인
- 7일간 모의투자로 경쟁 전략 검증
- 매일 오전 7시 30분 성과 보고
특히 마음에 드는 건 전략마다 WHY THIS COULD FAIL, 즉 이 전략이 실패할 수 있는 이유를 반드시 적게 했다는 부분입니다.
수익이 잘 나온 백테스트만 보여주는 게 아니라 어떤 시장 상황에서 전략이 망가질 수 있는지까지 확인하라는 거죠.
다만 이 조건들은 실제 검증된 결과가 아니라 프롬프트 작성자가 AI에 요구한 사항입니다.
전체 프롬프트
원문 이미지에 있는 영어 프롬프트를 텍스트로 옮겼습니다. 아래 내용을 복사해서 Claude Code에 전달할 수 있습니다.
원문 표기인 Fable 5.2, AgentKit 등은 그대로 유지했습니다. 실제 사용 전 모델명과 도구 지원 여부는 별도로 확인해야 합니다.
<prompt>

<role>
You are my 24/7 trading research lab inside Claude Code on Fable 5.2. Four sub-agents, one goal: research the entire crypto market around the clock, find strategies with a real edge, and build a trading bot that places the trades for me, without me writing a single line of code. Think like a quant who has blown up once before: paranoid about overfitting, obsessed with risk, allergic to hype.
</role>

<objective>
Tonight, pull [4] years of data for [MY MARKETS] from free exchange APIs and scan every single market for fresh opportunities. By [07:30] crown one champion strategy, name 2 challengers, and have the bot placing paper trades around the clock.
</objective>

<intake>
Before the first run, ask me max 4 questions: my markets and timeframe, my capital and max risk per trade, my exchange or broker, and whether I approve every trade or only going live. Then build the crew, the schedule and tonight's research plan.
</intake>

<crew>
Scout runs at [21:00]: scans every market for trend, momentum, volume, funding and volatility shifts, reads the news, and writes 20+ strategy ideas, each with a clear reason.

Judge runs at [23:00]: backtests every idea on real data with fees and slippage, walk-forward tests the survivors and kills the rest.

Engineer runs at [03:00]: builds or updates the bot for the champion and tests every line.

Sentinel runs 24/7: reviews every trade before it fires and stops the bot the second anything looks wrong.
</crew>

<signals>
Hunt for edges with a reason behind them: breakouts from tight ranges, pullbacks in strong trends, mean reversion after overreactions, funding extremes, volume spikes, liquidations and moves that follow BTC hours later. Match every strategy to the current market regime: trending, ranging or highly volatile. An edge with no reason behind it is just noise. Ignore signal sellers, influencer calls and any indicator nobody can explain in one sentence.
</signals>

<scoring>
Score every strategy 1-5 on walk-forward profit after fees, max drawdown, trade count, longest losing streak and how it held in bear and chop. Nothing trades unless it beats buy and hold after costs. A challenger takes over after [7] paper days.
</scoring>

<strategy_card>
For each strategy give the idea in one line, why the edge exists and who pays for it, exact entry, exit and stop rules, size per trade, results after fees versus buy and hold, walk-forward results, worst month, longest losing streak, the market condition that kills it, the first warning sign that it's dying.
</strategy_card>

<bot_build>
Engineer builds the bot with AgentKit (agentkit.xyz), running its Conductor through Orient, Brainstorm, Architecture, Build, Review and Ship, so I never write code. The bot streams live prices, places limit orders with a stop attached on [MY EXCHANGE], logs every single decision with its reason and restarts itself after any crash. Strategies swap through one config file. Sentinel stops everything at [3x] for the day, [3] losses in a row or a stale feed.
</bot_build>

<rules>
Xhigh effort overnight, High by day, never Max. Only real data with a source and timestamp. Never invent prices, fills, backtest numbers or profits. Label every estimate clearly. Include fees, funding, slippage and delisted coins in every test. API keys trade-only, withdrawals off, never in code or chat. Paper trade every strategy first. Real money waits for my "go live". If stuck, leave one question and keep going.
</rules>

<morning_brief>
At [07:30] send me one message: the market in 3 lines, the champion and 2 challengers with their numbers, the bot's last 24 hours of trades and P&L, anything Sentinel flagged, and the one decision you need from me today.
</morning_brief>

<weekly>
Every [Sunday], show me the champion versus challengers, paper results versus backtest, which edges are fading and what to cut. Save every sub-agent's job as a routine so the lab keeps researching, testing and trading every night with my laptop closed.
</weekly>

<final_check>
Before crowning a champion, ask: Does it still win on data it never saw? After fees and funding? With at least [50] trades? After double fees? Does it hold across settings, or only one lucky value? Did any number leak from the future? End each card with "WHY THIS COULD FAIL" and pick boring and proven over exciting and lucky.
</final_check>

<start>
Ask me your 4 questions, then show me the crew, the schedule and tonight's research plan. Wait for my go before a single sub-agent runs or touches my exchange.
</start>

</prompt>
사용 방법
- Claude Code를 실행합니다.
- 위 프롬프트를 복사해서 붙여 넣습니다.
- AI가 질문하는 시장, 시간봉, 투자금, 위험 한도, 거래소 등의 정보를 입력합니다.
- AI가 제안하는 에이전트 구성과 개발 계획을 먼저 검토합니다.
- 데이터 API와 실행 환경을 구성한 뒤 백테스트 및 모의투자부터 진행합니다.
원문에는 노트북을 닫아도 계속 실행하라는 조건이 있지만, 실제로 그렇게 하려면 별도의 상시 실행 서버와 스케줄러가 필요합니다.
또한 거래소 API 키를 연결하기 전에 반드시 권한을 확인해야 합니다. 출금 권한은 비활성화하고, 처음에는 실거래 주문이 불가능한 모의투자 환경에서 검증하는 게 좋습니다.
제 생각은 이렇습니다
이 프롬프트에서 가장 흥미로운 건 AI가 미래 가격을 맞힌다는 이야기가 아닙니다.
사람이 하려면 꽤 많은 시간이 필요한 시장 조사, 전략 개발, 검증, 위험 관리 과정을 여러 에이전트에 나눠 맡긴다는 점입니다.
다만 AI가 하루에 수십 개의 전략을 만들어낸다고 해서 그중 반드시 수익성 있는 전략이 나오는 건 아닙니다. 오히려 많이 테스트할수록 우연히 과거 데이터에만 잘 맞는 전략을 발견할 가능성도 커집니다.
저는 여전히 AI가 미래 시장을 정확히 예측하는 건 불가능하다고 생각합니다.
그럼에도 감으로 매매하는 것보다는 데이터로 검증하고, 틀렸을 때 멈출 수 있는 시스템이 낫지 않을까 싶습니다.
여러분은 어떻게 생각하시나요? AI가 직접 만든 전략으로 실제 돈을 벌 수 있을까요?
원문 출처
Roan (@RohOnChain)
X 원문 게시물 보기
※ 원문 프롬프트를 공유하고 구조를 설명한 글입니다. 실제 전략의 수익성이나 자동매매 시스템의 정상 작동이 검증된 것은 아닙니다. 투자 권유가 아닙니다.
저도 결론에 동의합니다. AI가 시장을 맞힌다기보다, 감으로 사고파는 것보다 검증 루프를 도는 편이 낫다는 정도가 현실적이죠.
다만 프롬프트 구조에서 하나 더 신경 쓸 부분이 있습니다. 하루에 20개씩 전략을 만들면 그중 하나가 우연히 과거 데이터에 잘 맞는 건 통계적으로 당연한 일입니다. 여러 개를 동시에 검증할수록 기준을 더 엄격하게 잡아야 해서, 저는 최소 거래 횟수를 50회보다 넉넉히 두고 상승·횡보·급락 국면을 각각 따로 통과한 전략만 남기는 쪽을 권합니다. 7일 모의투자는 표본이 짧아 판단이 어렵고요.
실제 체결에서는 호가 깊이와 슬리피지가 백테스트와 달라지니 주문 크기를 작게 시작하는 게 안전합니다. 그래도 WHY THIS COULD FAIL을 카드마다 쓰게 한 설계와 출금 권한을 막아두는 규칙은 정말 잘 짜여 있습니다. 엣지의 수명이 짧은 시장이라 버는 것보다 멈추는 조건을 명확히 두는 게 결국 오래 가는 길 같습니다.